Part one
Part one: the specs, before any code
Before there was an app, or an engine, or a phone, there were six documents about how something should behave.
Read this part in full
The specs came first
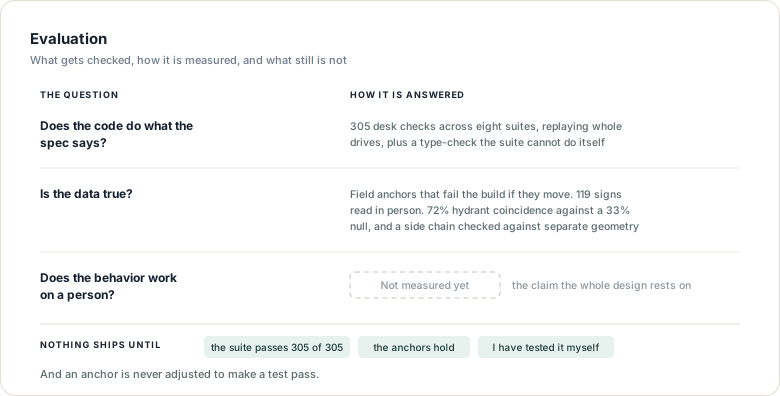
Six documents in five days, and not one of them has a screen in it. What kind of relationship this thing was proposing to have with a person. Which of its jobs it could be trusted to do alone. What it must never do under any setting. How it should talk when it isn't sure, which turned out to be most of the time.
I decided the agent's character before I knew whether any of it was buildable. Written down like that it sounds backwards. It is the single decision I would repeat without changing, because nearly every hard call in the next thirty days had already been answered in one of those files, and the calls that hadn't were the ones that took a whole day.
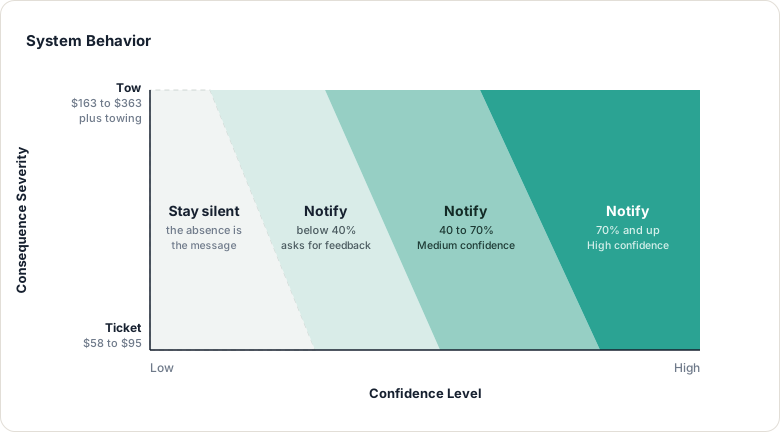
One line from the behavioral spec did more work than the rest of the month combined: doubt resolves toward speaking, not toward silence. A false alarm costs a few seconds. A missed ticket costs money and a tow. Those are not the same price, so the agent has to be more sure a spot is safe before it stays quiet than it has to be that a spot is risky before it speaks up. I had no idea how many times I would end up pointing at that sentence.
An engine with nowhere to put it
The rules came before the app that would use them. By the fifth there were 61,829 scored parking rules in a database, worked out from just under nine million tickets the city had written, and no iPhone project anywhere.
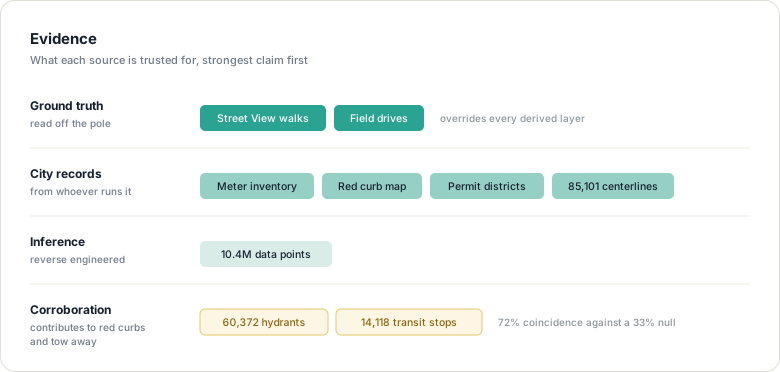
The idea is simple and slightly ridiculous. Los Angeles has never published a complete list of where you can and can't park. It does publish every ticket it issues, with the violation and roughly where. A ticket is the city saying, on the record, that a rule existed at that spot at that time. Enough of them and the rule comes back into focus. I tested it on one month of data before committing to anything and it produced 148 blockface rules for a single neighborhood with confidence scores that spread from 0.39 to 1.00, which is exactly what you'd want. Some things it knows. Some things it's guessing at.
Alongside the rules: 85,101 street segments, 60,372 fire hydrants, 34,943 metered spaces, 864 sweeping routes, 155 permit districts. The city, reassembled from the pieces it publishes separately and never joins up itself.
Part two
Part two: five field drives
Five days, five drives, and the approach I had spent two weeks designing did not survive the fourth one.
Read this part in full
Xcode to a phone, in a day
The log records this whole arc as a single line, and it deserves to stay one: Xcode project, then the simulator, then my nineteen mockups arriving, then a home screen built to them and running on real data, then the whole thing on my iPhone. Roughly twenty commits by the end of the night.
The app's first act on arrival was to count its own rules twice. Once with a plain count, once by stepping through every row, because a partially copied database will report a perfectly plausible total and then fail halfway through a read. 61,829 rules, 85,101 segments, 3,568 meter limits, 51,494,912 bytes, matching the count taken off the source file before Xcode existed. It's a small thing. It's also the first time the project checked itself against itself and I remember being relieved that the numbers matched.
The first two drives
The app met a street and broke in five ways no desk test had found. The motion detection flickered. Location fixes went stale. There was no heading at the moment of parking, which matters because heading is how you know which curb you are against. The detector announced a park while I was still driving. And the home banner never left demo mode. All five fixed the same day, with tests that replay the actual field log so the bug can never quietly come back.
One thing worked first time. The first curb the app ever guessed: heading 199.7 degrees, southbound on Las Palmas, west side. Correct. A sample of one, and I wrote it down anyway because it was the first time the whole idea had touched a real street and not been wrong.
Then I parked on a red curb and the app told me to pay the meter.
That one turned into the day's real work. Rules lived at the level of a blockface, a whole side of a whole block, and a ten meter stretch of red paint is invisible at that grain. So I took 1.5 million red curb citations, projected each one along its street, split them by side, and clustered them. Out came 28,619 red zones on 12,221 segments with a median length of about ten meters, which is the length of actual paint rather than the length of a block. To check they were real I looked at where they landed: 72% sit at a fire hydrant, against 33% for the same zones shuffled to random positions. And my own park that afternoon, at 55.7 meters along the block, fell inside the detected zone at 25 to 60. The mistake became the test case.
The third drive, and the phone that fell asleep
This was the drive that answered every open question about background detection, all in the bad direction, and none of it was visible until I added breadcrumbs to the log.
The app showed Parked at every red light. The real park was created sixteen minutes late, at the moment I picked the phone back up, and it was placed 700 meters from the car, at my feet where I was standing on a block with completely unrelated rules. It was never announced. Nothing was scheduled. The two hour timer I had specifically driven there to watch start did not exist.
What the drive settled, permanently: the background timer does not fire. Motion sensing delivers nothing once the screen locks. The one stream that keeps arriving is location, and it is the only reason the app stayed alive at all. Any logic that could only move forward on a tick or a motion event was dead the moment the phone went in my pocket.
Seven fixes, each with a regression test replayed from the log. The test suite went from 37 checks to 48, and I verified the ten new ones fail against the old detector, reproducing the drive exactly: zero parks created, zero announced, position at infinity.
Fourteen decisions before dinner
Between the third drive and the fourth I sat down with the scenario matrix and ruled on every situation nobody had decided yet. Fourteen of them. Seven became working code and tests before the end of the day, which is where the 42-check policy suite comes from.
There's a caution in the log from that session that I've kept ever since, because it was already the second time it had bitten. The suggestion column in the matrix was the agent's, not mine, and suggestions were never to be promoted into decisions just because they'd been sitting in the sheet long enough to look settled. Where I overruled a suggestion, the overrule governs.
The bus stop
I parked at a DASH stop with the engine running. The phone's motion sensor flickered between automotive and stationary every second or two, and each flicker killed the park it was in the middle of settling. Eleven detections. Ten cancellations. The correct warning, "Do not park here, red curb, $93", finally arrived five minutes late, as I was pulling away.
Earlier in the same drive, creeping 400 meters toward a red light in traffic had read as the phone walking away from a parked car, and the app pushed a loading zone warning mid-drive while the motion sensor was saying automotive the entire time. Two failures, opposite directions, same source.
I fixed both that night. But I also wrote down, for the first time, that I might be fixing the wrong thing.
The pivot
Four drives had shown the same thing from four angles. Inferring the park from sensors was not a part of the system with bugs in it. It was the source of the noise, and every silent failure I had traced back to the same place.
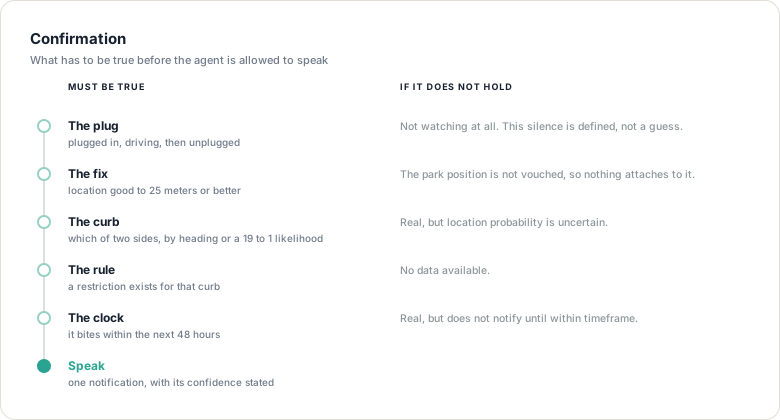
So I stopped inferring. Plug in to drive, unplug where you park.
It asks something of the person, which is the sort of thing you are trained not to do. I took the trade because of what it buys. The plug bounds the app's attention: plugged and driving is the only state where it watches at all. Never plugged is not a failure, it is the app being deliberately asleep. Which means that when Curb is quiet, the quiet means one thing instead of three. The entire project is about not letting silence be ambiguous, and it had taken me four drives to notice that the detection layer was the biggest source of ambiguous silence in the system.
The build split into its own line that morning, tagged at the moment of the decision, and never merged back.
Drive five
The first weekend on the new contract. The findings document opens by saying the detection layer produced zero complaints, and that everything left was in the data or the decisions. Which is where the pivot had said the problem would go.
So the problems were more interesting. At 737 N Vista on a Sunday afternoon, the app said Good Standing, move by Monday 10am. The Monday sweeping was right. But the sign also said two hour parking, and no parking after midnight, and neither of those made it into what I was told, so the thing I actually needed to do first was invisible.
Same block, different lesson. The app thought the whole segment was metered. The meters were three physical spaces at the corner, 95 meters from where I'd parked, responsible for 210 of the 216 metered tickets on that street. The data had flattened three corner meters into "the segment is metered", the same disease the red curb work had just cured, and the inventory carried per-space coordinates the whole time.
Part three
Part three: the tickets become rules
The tickets had been trying to tell me things. This is the week I started listening, and found a whole city missing.
Read this part in full
What the tickets were actually saying
Fines first. I had been carrying them as lookups and they were measurable, so I computed what the city actually charged. Peak hour had been sitting at $68 from a single sample and is really $163. Bus zones are $293, the most expensive mistake in the dataset.
Then what I'd been treating as one bus restriction split cleanly into two on timing alone. "Exclusive for buses" puts 52% of its tickets in the 4 to 6pm hours and about 1% at weekends, which is a rush hour lane. "Parking in bus zone" is flat across all seven days, which is a permanent stop. Merging them, which I had been doing, turned a weekday peak into a round the clock ban.
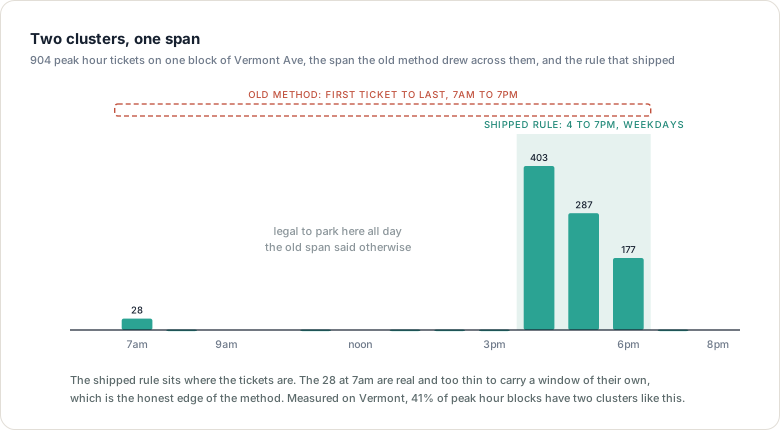
Then a real error, not a refinement. I'd been reading a restriction's hours as one span from the first ticket of the day to the last. That collapses "no parking 7 to 9 and 4 to 6" into "no parking 7am to 6pm" and tells someone a curb is off limits through a middle of the day when it's completely legal. Measured on Vermont, 41% of peak hour blocks have two windows. The fix was to look for the gaps in the hourly distribution instead of the edges, and the bimodal blocks that had scored badly under the old method scored well under the new one, because the shape had been wrong rather than the data.
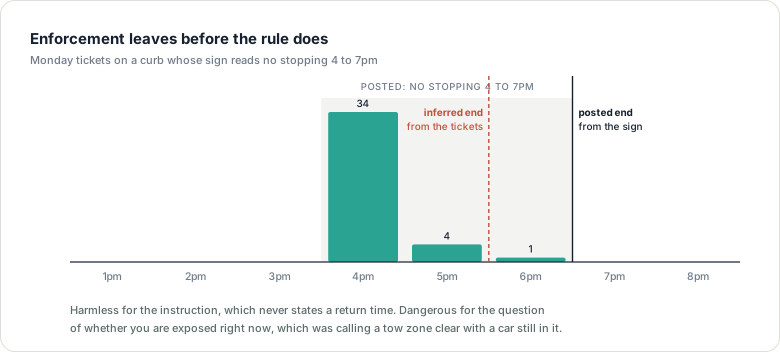
Then the one that could have cost somebody a tow. Enforcement sweeps through at the start of a window and leaves. On a curb posted four to seven, the tickets run 34 at four, four at five, one at six. So the inferred end lands at six for a rule that runs to seven. Harmless for what the app tells you to do, because it never states a return time. Dangerous for the question "am I exposed right now", which was declaring a tow zone clear while a car sat in it. Erring late costs a redundant warning. Erring early costs the tow. It now errs late.
And in the same week, a dataset I'd fetched and stored on day one and never read: 864 posted sweeping routes, each with a real start and end time. Every one of the 61,829 rules had been inferred from tickets while the posted answer sat one table over. The window end is exactly the thing tickets cannot tell you, and it had been there all along.
The city clerk had written it down
Council files quote sign text verbatim. That sounds obvious once you know it and I had no idea. A greppable index leads to a file number leads to a PDF with a text layer, and in the PDF is the city, in 1990, establishing a permit district "with six separate parking restrictions". Heterogeneity is the city's own word. It goes down to the side of the street: the west side of Gardner gets one scheme, the east side gets another the menu didn't even have.
One file settled something a drive had left open. Franklin is a boundary street. The council put its south side in one permit district and its north side in a different one. So the tempting shortcut, assume the dominant district for a segment that has no clear signal, would have asserted the wrong district's rules for a curb the city had specifically placed elsewhere. Franklin stays untouched until districts are assigned per curb rather than per block.
Which side of the street
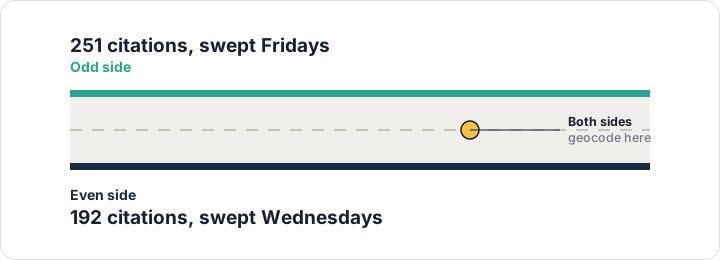
The correction that changed the shape of everything. A rule does not belong to a block. It belongs to a curb, and the two curbs on one block routinely have different rules. On one stretch of Vermont the odd side drew 251 Friday sweeping tickets and the even side drew 192 Wednesday ones. Same block, opposite curbs, different days. Across every block where both curbs could be resolved, 87% are like that.
I audited 37 blocks by hand, in Street View, over two days. The first two groups passed outright, 15 of 15 and 12 of 12, which is what let me loosen the gates. The third group failed nine times out of ten, and that failure was the valuable one. On a small share of streets the address ranges are attached to the wrong side, mirrored. When the house numbers on the tickets disagreed with the geometry, the house numbers were right, nine times out of ten, and there is now a guard that refuses to assert a side when the two contradict.
The audit is also where I learned to walk. The first time I read signs off Street View I read "THURSDAY" at two spots on Catalina and assigned them to opposite curbs, then built a whole schedule change story on top and committed it. Both readings were the west curb. I had turned the camera around without noticing that turning around swaps left and right. I caught that twice in one afternoon, and it became the first rule in the walking manual marked as law: never attribute a sign to a curb from the camera heading alone. Anchor it to what is physically behind the sign.
Five blocks away
I parked near Melrose and the app announced 929 N Stanley, West Hollywood. Five blocks from where the car was.
The log explained it. The park had been frozen from a location fix that was 291 seconds old, taken at 11.7 meters per second, southbound. That's where the car was five minutes before I unplugged, and the detector had accepted it without looking at the age or speed sitting right there in its own log fields. Worse, the morning's park had gone 94 minutes without a single location fix. The app was being suspended mid-drive, and plug events during suspension were never delivered. It had been chronic for two days and nothing had said so.
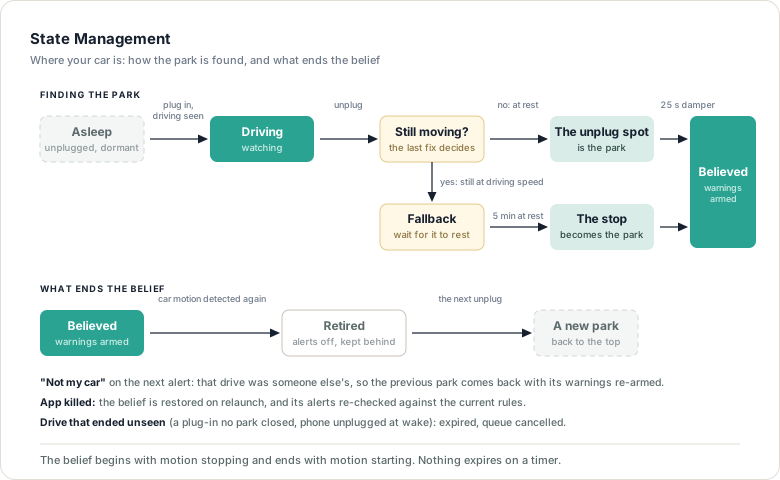
The fix has three parts and the first one is the design. At the unplug, the fix has to vouch for itself: recent, and not showing driving speed. A fix that can't vouch still creates the park, but flagged as position uncertain, and the first genuine fix during the settling window replaces the position outright, with the heading deliberately thrown away so the curb is refused rather than guessed from a direction the car held blocks earlier. If nothing better arrives, the announcement is the honest version: check the signs where you parked. No street named. No rules resolved at a place the car merely drove past.
The other two parts were plumbing that heals itself and instrumentation that stays on outside test sessions, so the next starvation names its own cause instead of leaving me to do forensics on fix ages.
A city inside the city
I checked a spot at 715 N San Vicente and the app had nothing, because I had crossed into West Hollywood without any way of knowing. LA's data stops at a border you cannot see from the car. Two cities hold centerlines for the same boundary streets, sometimes less than a meter apart, and the app had been quietly matching against whichever one it hit first.
So I went to find out what West Hollywood publishes. It is almost nothing. Forty-three datasets on the portal, and no citations, no meters, no curb paint, no permits. Street sweeping schedules exist as seven CAD drawings from 2008, one per weekday, exported from MicroStation with no text layer and no hours, seventeen years stale, and downloadable only through a browser because the city's edge network blocks everything else. The inference engine that had just produced 61,829 rules for LA had no fuel here whatsoever.
What unlocked it was staring at the maps long enough to notice that the color is painted on the curb that gets swept, not down the middle of the street. Every one of Monday's 107 strokes sits at distance 0.000 from a curb line. The maps had been telling us the side the whole time, in the only language a 2008 CAD export has.
Decoding all seven took a day. Five weekday maps with two different legend dialects, a commercial map with multi day zones, and the alleys, which turned out to have no schedule of their own because they follow whichever neighborhood they're in. Then a smaller discovery along the way: a meter decal on Curson listed Harvey Milk Day as a holiday, which LA does not observe, which sent me to audit every neighbouring city and find that Santa Monica keeps three different holiday lists for three different restriction types and Beverly Hills suspends permit parking on holidays while LA enforces it. Holidays are per city and per restriction class. Nobody tells you this.
West Hollywood shipped on the 14th. 698 segments, 653 sweeping rules read per curb, correct on every one of the 61 curbs I had personally stood at. The city went from a refusal message to an answer in two days, with a standing caveat that it only knows sweeping.
Part four
Part four: the walkers, now its own case study
From August 11 the story of the sign-reading agents is its own case study: The Agentic Walkers, told day by day.